
For SRE and platform teams
Uptime, alerts and incident evidence in one place
Check sites, APIs and hosts from several regions. Send alerts where your team already works, keep users informed on a status page, and investigate incidents with the evidence in front of you.
What Supercheck fixes
Alerts that nobody trusts
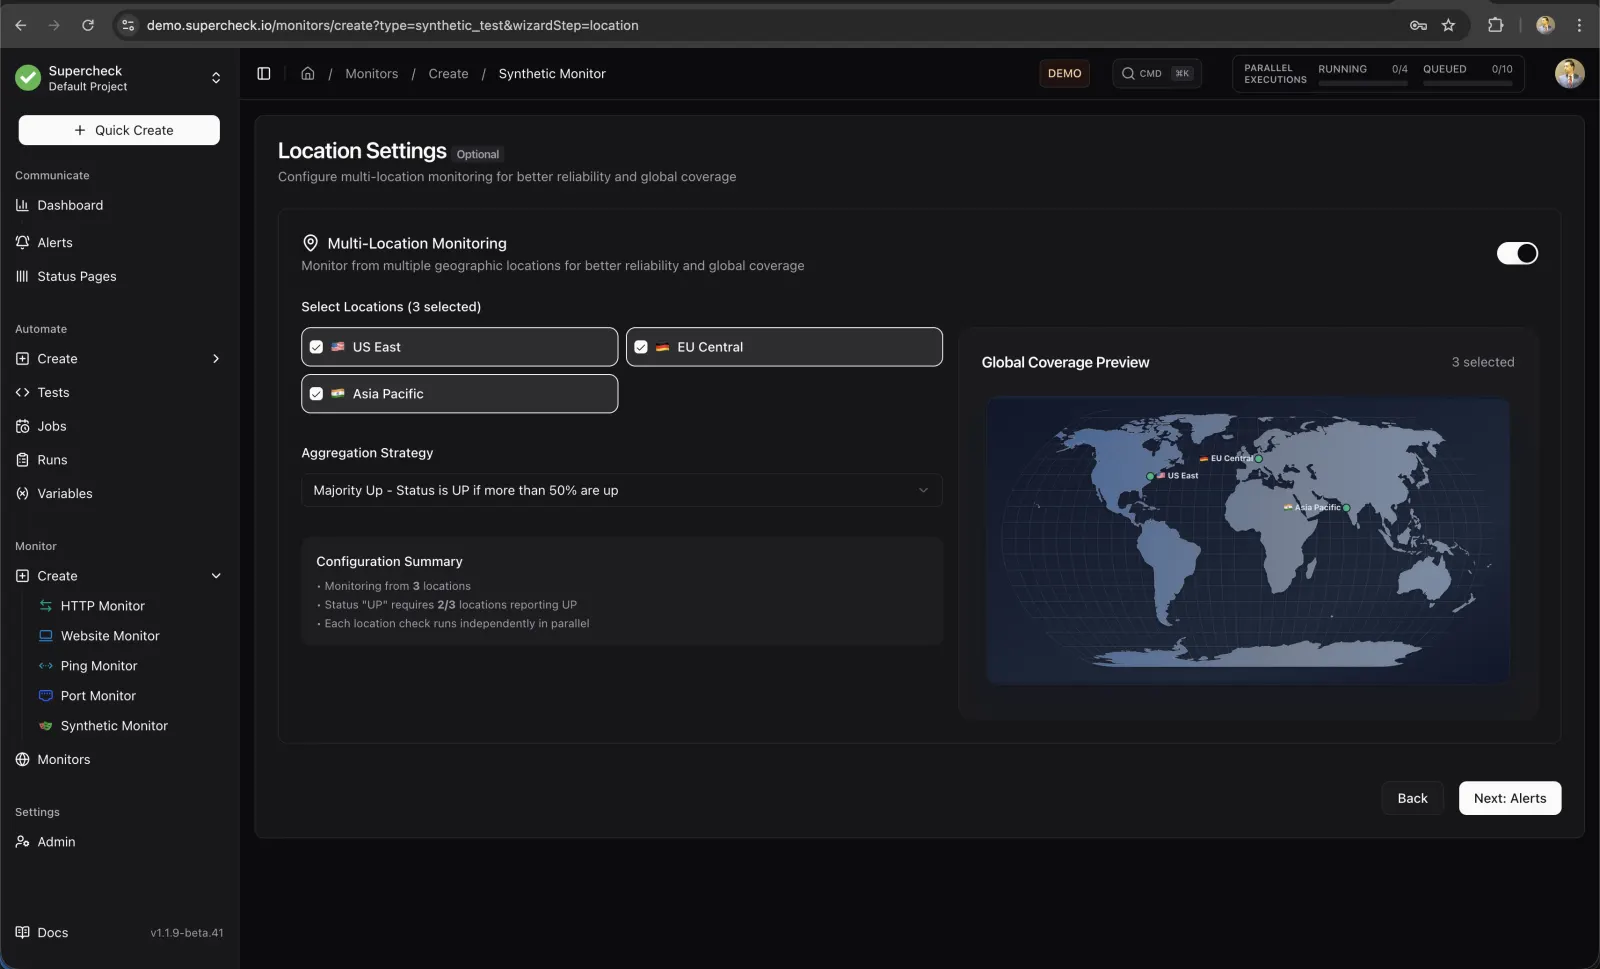
One failed probe should not page anyone. Set how many consecutive failures raise an alert, and how results from several regions combine before a monitor goes down.
Users hear about outages first
Link monitors to status page components and post incident updates that reach subscribers by email, Slack, webhook or feed.
Evidence scattered across tools
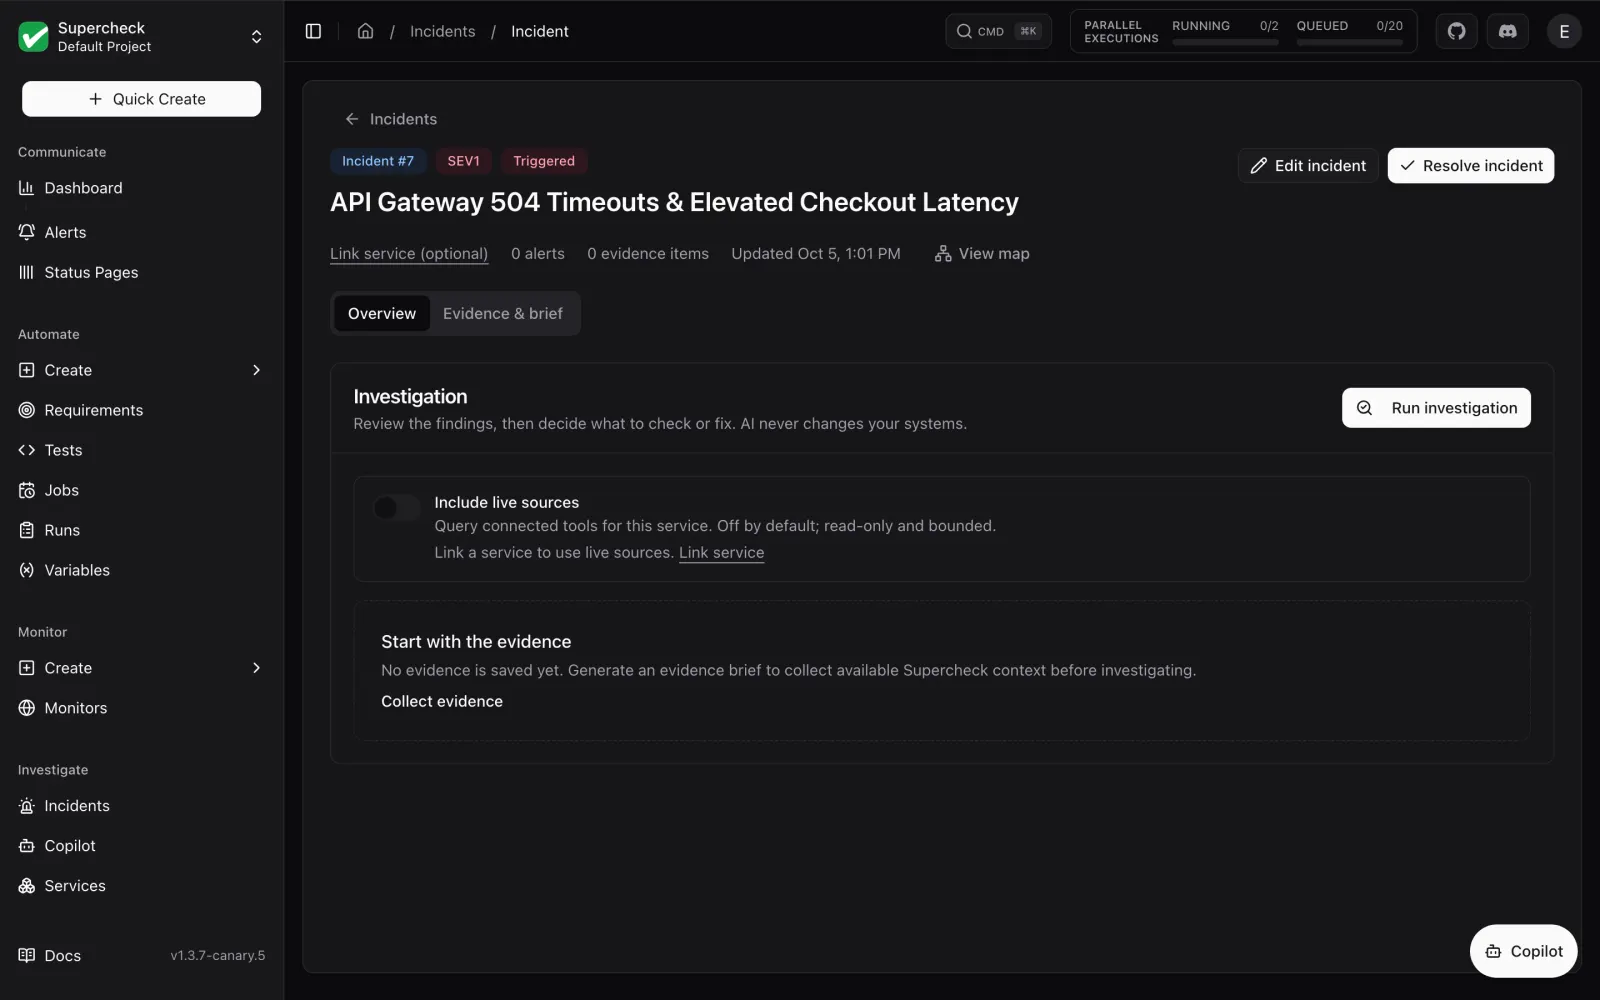
AI SRE reads metrics, logs, traces, deploys and errors through read-only connectors, and cites what it found so you can check it.
Monitor from several regions
Run HTTP, website, ping and port monitors with check intervals down to one minute. Supercheck Cloud will check from Europe, North America and Asia Pacific; self-hosted installs check from wherever you run workers.
- Website monitors track SSL certificate expiry
- Failure and recovery thresholds from 1 to 5 consecutive checks
- Regional results combined with a strategy and threshold
Route alerts to the right channel
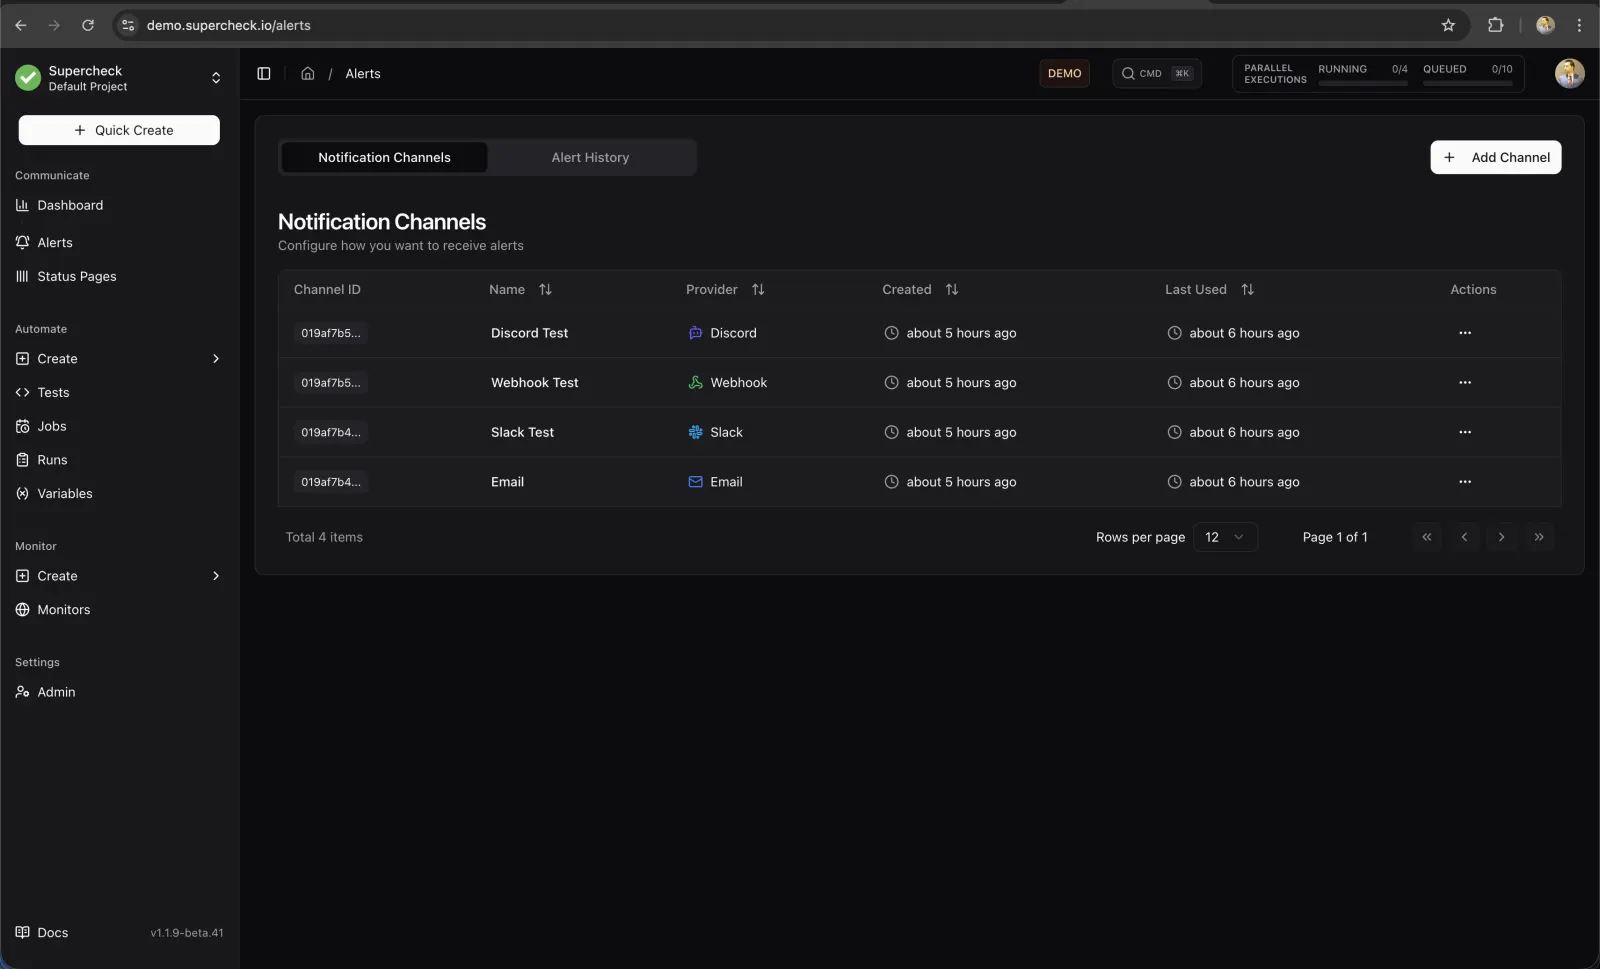
Send failure and recovery alerts for monitors and jobs to the tools your team already watches.
- Email, Slack, Microsoft Teams, Discord, Telegram and webhooks
- Alert history for every monitor and job
- Test a channel before you rely on it
Investigate with cited evidence
Open an incident from an alert, then run a read-only investigation. Findings link back to the evidence, and you decide what to change.
- Prometheus, Grafana, Loki, Tempo, AWS CloudWatch, Elasticsearch and OpenSearch
- Kubernetes, Sentry, Datadog, GitHub, GitLab, PagerDuty and Opsgenie
- Private Agent reaches systems inside your network without inbound access
Keep users informed
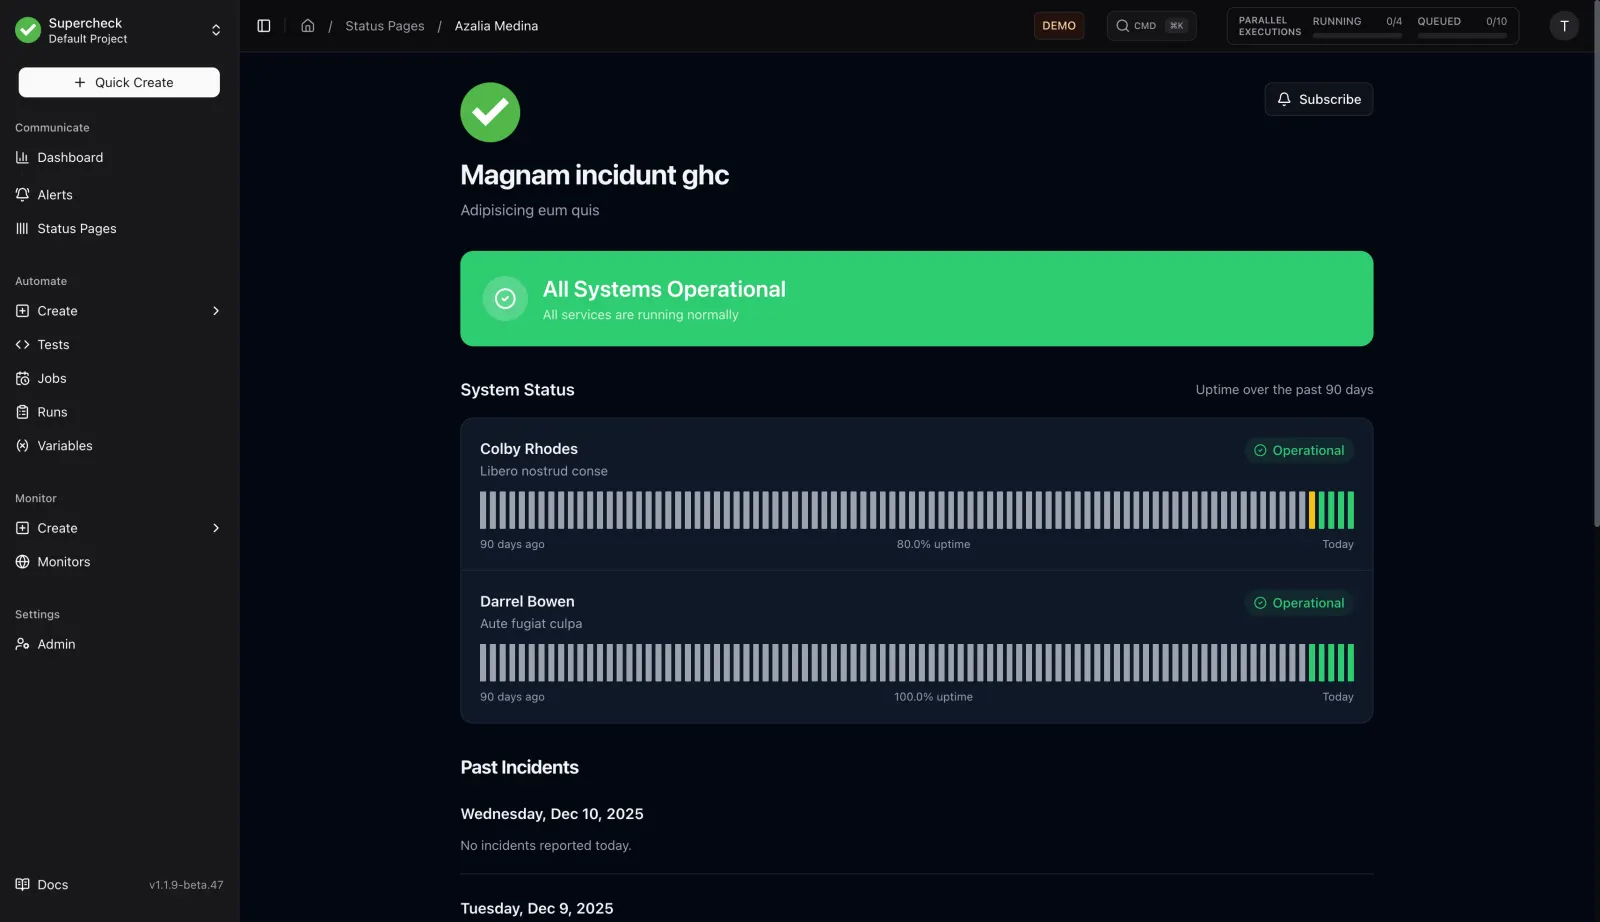
Publish a status page on your own domain with components, incident history and subscriptions.
- Components linked to monitors
- Email, Slack and webhook subscribers, plus RSS and calendar feeds
- Custom domains
Run it next to the systems it watches
Self-host Supercheck on your own Linux servers with Docker Compose, or explore the live demo first.